Turn scanned documents into checked data
Fields pulled from licences, invoices, IDs and contracts by vision models, checked by validation rules and sent to a person when confidence is low.
Overview
Trade licences, Emirates IDs, invoices and contracts arrive as scans, photos and PDFs in Arabic and English. Someone types the fields into a system, and mistakes surface weeks later.
We use vision-capable language models to extract the fields you need, then check them with rules: date formats, licence number patterns, totals that add up, expiry dates in the future. Anything that fails a rule or scores low goes to a review screen before it reaches your system.
Signs you need this
- Staff retype the same fields from documents into your systems every day
- Traditional OCR templates break whenever a layout changes
- Data entry errors are found late, during audit or renewal
- Arabic or mixed-language documents are handled entirely by hand
What you get
- Document schemas
- For each document type, the fields to extract, their formats and the rules that make a value valid.
- Extraction pipeline
- Upload or email intake, page classification, model extraction and structured output as JSON.
- Validation rules
- Format checks, cross-field checks such as totals and dates, and lookups against your existing records.
- Human review screen
- A queue showing the document beside extracted fields, with failed checks highlighted for correction.
- Integration
- Approved data written to your database, ERP or CRM through its API, with the source file kept alongside.
- Accuracy report
- Field-level results on a labelled test set of your own documents, rerun whenever the model or prompt changes.
How the work runs
- 1
Sample and schema
1 to 2 weeks
We collect real documents, agree the fields and rules, and label a test set.
- 2
Extraction build
2 to 4 weeks
We build intake, extraction and validation, and measure results on the test set.
- 3
Review and integration
2 to 3 weeks
We add the review screen and connect approved output to your target system.
- 4
Pilot
2 to 3 weeks
Your team processes live documents through the system while we fix failure patterns.
Timings depend on the size of your estate. The assessment fixes them before any build starts.
What you can check afterwards
- Every extracted record passes its validation rules or is held for review
- Reviewers see the source document and failed checks on one screen
- Field-level accuracy on your own test set is recorded and rerun on each change
- Approved records arrive in your target system with a link to the original file
Tools we work with
- Claude
- GPT-4o
- Qwen2.5-VL
- Amazon Textract
- Azure AI Document Intelligence
- Python
- Pydantic
- PostgreSQL
- Next.js
- Amazon S3
From our work
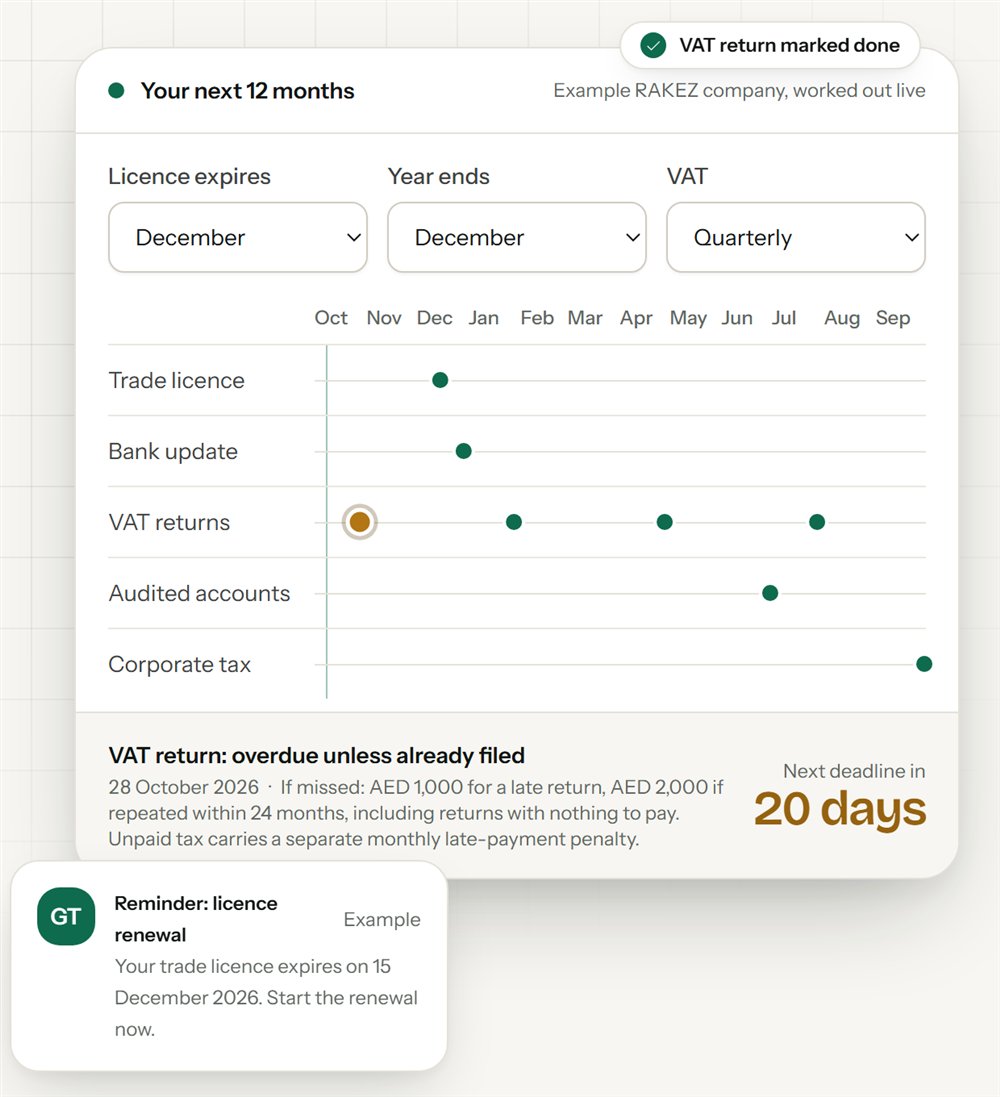
OpsBreak's own product
Get Tajdeed: a bilingual compliance calendar on one server
A bilingual SaaS product run on a single low-cost server
Questions buyers ask
- How accurate is it?
- It depends on your documents, so we measure it on a labelled sample of them before go-live. Validation rules and human review catch what the model misses.
- Do ID and licence scans leave the country?
- Not if you need them to stay. We can use a self-hosted vision model or a provider endpoint in your region, and store files only in your account.
- Does it read Arabic?
- Yes. Current vision models read Arabic and English, and we include Arabic documents in the test set to confirm it on your files.
- What access do you need?
- A sample of real documents, ideally a few hundred per type, plus test access to the system the data goes into.
Talk to us about intelligent document processing.
Tell us what you run and where. We reply within one business day with questions or a quote.